Learn how AI data pipelines work and how smarter collection, processing, storage, governance, and data lifecycle decisions can support more efficient and sustainable AI systems.
Artificial intelligence gets most of the attention at the model level, but every useful AI system depends on what happens before and after a model runs. Data must be collected and delivered in a usable form. Those steps make up a data pipeline. For organizations concerned about sustainability, pipeline design matters because inefficient data movement and processing can consume computing resources without improving the final result.
Where an AI Data Pipeline Begins
A pipeline starts with data sources. Depending on the organization, these might include business applications, website activity, equipment sensors, transaction records, customer interactions, satellite imagery, or environmental monitoring systems.
The first challenge is deciding what should actually enter the pipeline. Collecting everything because it might become useful later creates storage costs and makes governance harder. It can also increase the amount of data that must be transferred and processed.
Raw Data Usually Needs Work
Information from different systems rarely arrives in a consistent form. One source may record dates differently from another. Sensor readings can be missing, duplicated, or reported in different units. Customer databases may contain several records for the same organization.
The processing stage identifies and corrects these issues before data reaches the model. Common tasks include removing duplicates, standardizing formats, handling missing values, validating measurements, and connecting related records. This stage affects AI quality directly. A sophisticated model trained on inaccurate or inconsistent information can still produce unreliable results.
Storage Decisions Affect Efficiency
Data may pass through databases, data warehouses, data lakes, or other storage environments before reaching an AI application. Each approach serves different needs, but retaining unlimited amounts of information indefinitely can create unnecessary infrastructure demands.
Organizations should establish retention rules based on operational, legal, analytical, and historical requirements. Some datasets need long-term preservation. Others lose much of their value quickly.
Granularity matters too. A sensor that records a measurement every second generates 86,400 readings per day. If minute-level averages are sufficient for long-term analysis, keeping every raw reading forever may offer limited additional value.
Processing Turns Data Into Model Inputs
AI models generally cannot use every raw record exactly as it arrives. Pipelines often transform data into features that make patterns easier for a model to identify.
For predictive maintenance, raw temperature readings might be converted into variables showing average temperature, maximum temperature, or changes over a particular time period. An energy-management model could combine electricity consumption with weather, occupancy, and operating schedules.
Processing can occur in batches or closer to real time. Real-time processing is useful when decisions need to happen immediately, but it usually requires infrastructure that remains available continuously. Batch processing may be sufficient for reports, forecasts, or models that update periodically.
Models Are Only One Stop in the Pipeline
Once prepared data reaches an AI model, the pipeline still has work to do. Predictions need to reach the people or systems that can use them.
A model predicting excess energy consumption might send results to a building management platform. A manufacturing model could flag equipment for inspection. A supply chain model might update demand forecasts used by purchasing teams.
Feedback is valuable here. If users repeatedly ignore certain alerts because they are inaccurate or irrelevant, that information should flow back into model evaluation.
Sustainability Requires Measuring the Entire System
Discussions about AI sustainability often concentrate on model training. Training can require significant computing power, especially for large models, but everyday data infrastructure also consumes resources.
Storage systems run continuously. Data moves across networks. Processing jobs may execute thousands of times. Models can be retrained or queried more frequently than necessary.
Organizations should examine the full pipeline for redundant copies, abandoned datasets, unnecessary transformations, excessive retention, and workloads running more often than their business purpose requires.
The people managing these systems matter as well. Clear documentation and IT training solutions can help technical teams apply consistent practices around data quality, infrastructure use, security, and lifecycle management.
Governance Keeps Data From Becoming Digital Clutter
Data governance determines who owns information, who can access it, how long it remains available, and what happens when it is no longer required. Without clear ownership, old datasets tend to accumulate. Teams may create new copies because they do not know whether existing data is reliable. That duplication increases storage while making it harder to determine which version should be used.
A data catalog can help teams identify available datasets and their owners. Retention schedules provide a process for reviewing older information. Access controls reduce unnecessary exposure of sensitive records.
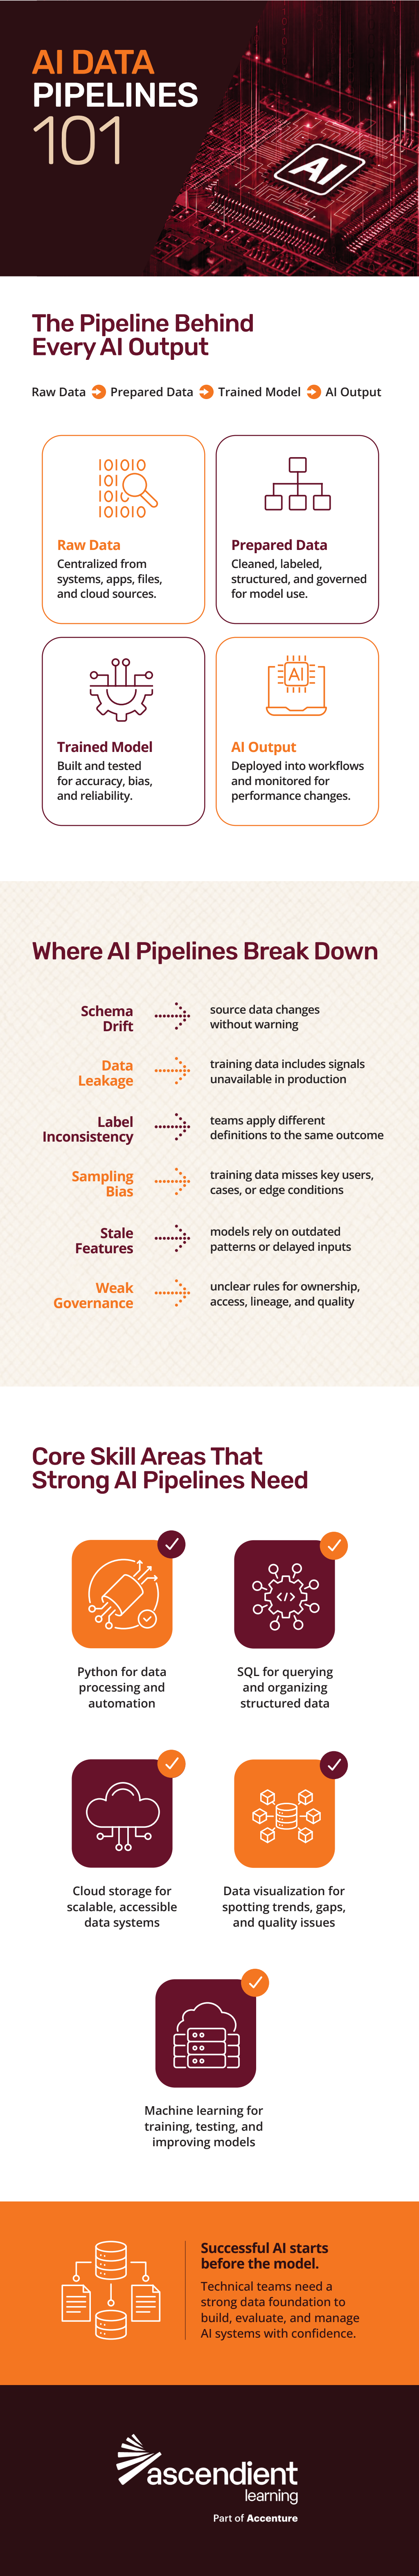
Sustainable AI does not mean avoiding computation whenever possible. It means making computing activity earn its place. Organizations that examine the entire data lifecycle can identify where additional processing creates genuine value and where it simply creates more digital overhead. For more information on AI data pipelines, feel free to look over the accompanying resource below.
Disclaimer:
This article is intended for general informational and educational purposes only and should not be considered technical, cybersecurity, legal, or data governance advice. AI infrastructure, data requirements, security obligations, environmental impacts, and regulatory requirements vary between organisations and applications. Businesses should assess their own systems, data practices, and compliance obligations and seek qualified technical or professional advice where appropriate.